Aligning protein-generative models to experimental fitness with ProteinDPO
[ad_1] Generative model alignment Generative AI applications are now routinely fine-tuned with feedback-based RL during
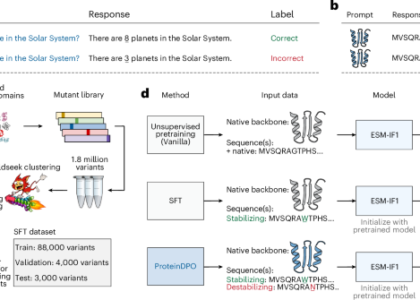
[ad_1] Generative model alignment Generative AI applications are now routinely fine-tuned with feedback-based RL during